The van der Corput sequence is the lowest discrepancy sequence known to exist. It was brought forward by one Johannes Gaultherus van der Corput in 1935 and is remarkably simple in implementation as it is a transformation of the sequence of natural numbers, where each element of the latter is reflected around the radix point. The original paper is inaccessible due to old age and even when one jumps over that digital wall, there are language barriers as van der Corput was Dutch.
Equal shares
If you're not familiar with discrepancy, it's the best known measure of non-uniformity of sequences which also happens to be extremely hard to compute for any non-trivial sequence (which is to say, any useful one). To say a sequence is uniformly distributed is to say that any subinterval of the interval on which the sequence is defined receives an amount of elements that is proportional to the relative length of the interval.
On the notation used
When it comes to notation, as sequences are ordered, we morph notation used for tuples which are also ordered. Nominally, it's \( (x_i)_{i\in\mathbf{N}} \), but some prefer to use curly braces. As we mentioned, sequences can be defined as functions which map from the domain of integers to the codomain of sequence elements (essentially, indices to objects). Which is to say \( (x_i)_{i\in\mathbf{N}} \) is a fancy way of writing \( S(i \mid i\in\mathbf{N} ) = x_i \). The \(x_i\) is merely a placeholder for something actually useful.
One such trivial example of a uniformly distributed finite (and seemingly useless) sequence defined on the \([0,1)\) interval could be easily constructed by taking the desired number of points \(N\) and using it in the definition as \( (i/N)_{i=0}^N \) which will give us an evenly spaced point set that for \(N=10\) looks like:
$$ \begin{split} (i/10)_{i=0}^{10} & = \left( 0, \frac{1}{10}, \frac{1}{5}, \frac{3}{10}, \frac{2}{5}, \frac{1}{2}, \frac{3}{5}, \frac{7}{10}, \frac{4}{5}, \frac{9}{10} \right) \\ & = \left( 0, 0.1, 0.2, 0.3, 0.4, 0.5, 0.6, 0.7, 0.8, 0.9 \right) \end{split} $$
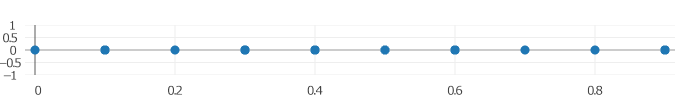
Consider the subinterval \([0, 0.1)\) which is a tenth of the full interval's length (measure) on which the sequence is defined. It receives exactly a tenth of all the points (of which there are \(10\) in this case). Perfectly uniform, trivial and utterly useless... Why? First of all, it's finite due to its dependence on the number of elements in a sequence. Second of all, it's implicitly ordered in ascending order, meaning that elements come off the "queue" predictably, consider the first four elements of the sequence separately:
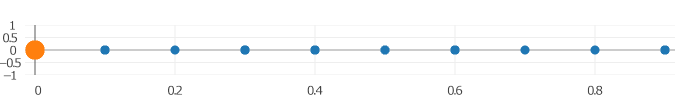
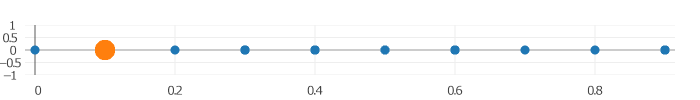
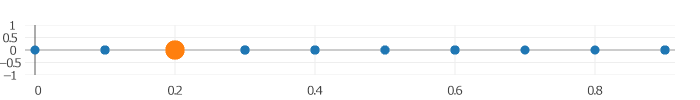
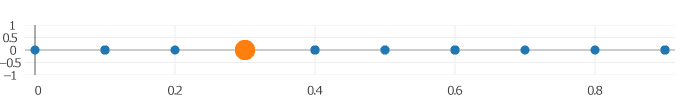
As expected, the upper half of the unit interval is completely devoid of elements at this point, making this a very uninteresting sequence to draw any kind of samples. Not to mention it is finite and depends on the number of points. But it is uniformly distributed, so it might be worth investigating it further. We do want our infinite sequence to be as uniformly distributed as possible. We've been looking at in the compact decimal encoding, but let's go to the "higher granularity representation" of the binary encoding (naturally, you could also choose octal or even ternary to see the same thing) and, for convenience, change \(N\) to \(8\) because a power of \(2\) in the denominator can have exact fraction representation (consider \(0.1_{(10)} \approx 0.0001100110011001101_{(2)} = 0.1000003814697265625_{(10)}\)):
$$ \begin{split} (i/8)_{i=0}^{8} & = \left( 0, 0.125, 0.25, 0.375, 0.5, 0.625, 0.75, 0.875 \right)_{(10)} \\ & = \left( 0.000, 0.001, 0.010, 0.011, 0.100, 0.101, 0.110, 0.111 \right)_{(2)} \end{split} $$
Notice how the most significant bits of the fraction are the least changing ones as the sequence progresses in order. Now notice what happens when we flip those bits, making the high frequency less significant bits switch places with the low frequency higher significance bits:
$$ \begin{split} (i/8)_{i=0}^{8} & = \left( 0.000, 0.001, 0.010, 0.011, 0.100, 0.101, 0.110, 0.111 \right)_{(2)} \\ & \rightarrow \left( 0.000, 0.100, 0.010, 0.110, 0.001, 0.101, 0.011, 0.111 \right)_{(2)} \end{split} $$
Take a look how the first four elements seed the unit interval:
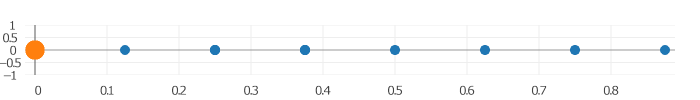
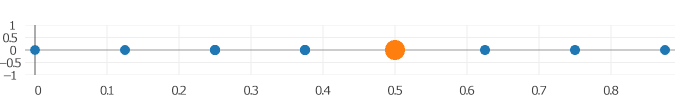
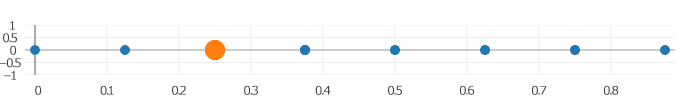
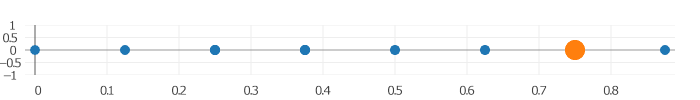
As you can see, much better coverage of the unit range. Again, if you look at the flipped bits, you'll notice that they're merely natural numbers in binary form reflected around the radix point, as shown in these examples: \(1_{(2)} \rightarrow 0.1_{(2)}, 10_{(2)} \rightarrow 0.01_{(2)}, 11_{(2)} \rightarrow 0.11_{(2)}, 100_{(2)} \rightarrow 0.001_{(2)}\)... This allows us to define the van der Corput sequence, without any dependence on \(N\) (thus infinite), as:
$$ \left( \sum_{k = 0}^{\log_2(i)+1}{d_k(i)2^{-k-1}} \right)_{i\in\mathbf{N}} $$
Where \(d_k(i)\) retrieves the \(k\)th digit for the reflection. Does the new sequence retain its uniform distribution? While we have no idea what is its exact discrepancy even in 2018. (or the discrepancy of any other non-trivial sequence) as it is extremely hard to compute, van der Corput and countless others have been working hard on providing a progressively decreasing upper bound on its deviance. Since its introduction in 1935., it is still the lowest discrepancy sequence in its class.
Many generalizations have been invented since in hopes of beating it, but also ones that make use of it in higher dimensions such as the Halton sequence. Given its low discrepancy results in great coverage of the domain and the associated random appearance, van der Corput sequence values are often called subrandom or quasirandom numbers and are extremely useful in many fields as a deterministic substitute for random values drawn from a uniform distribution, for example, Monte Carlo integration. I personally use the van der Corput sequence and its derivatives to solve a multitude of problems spaning anti-aliasing, terrain generation and realtime global illumination.